03/Selected work
File Intelligence
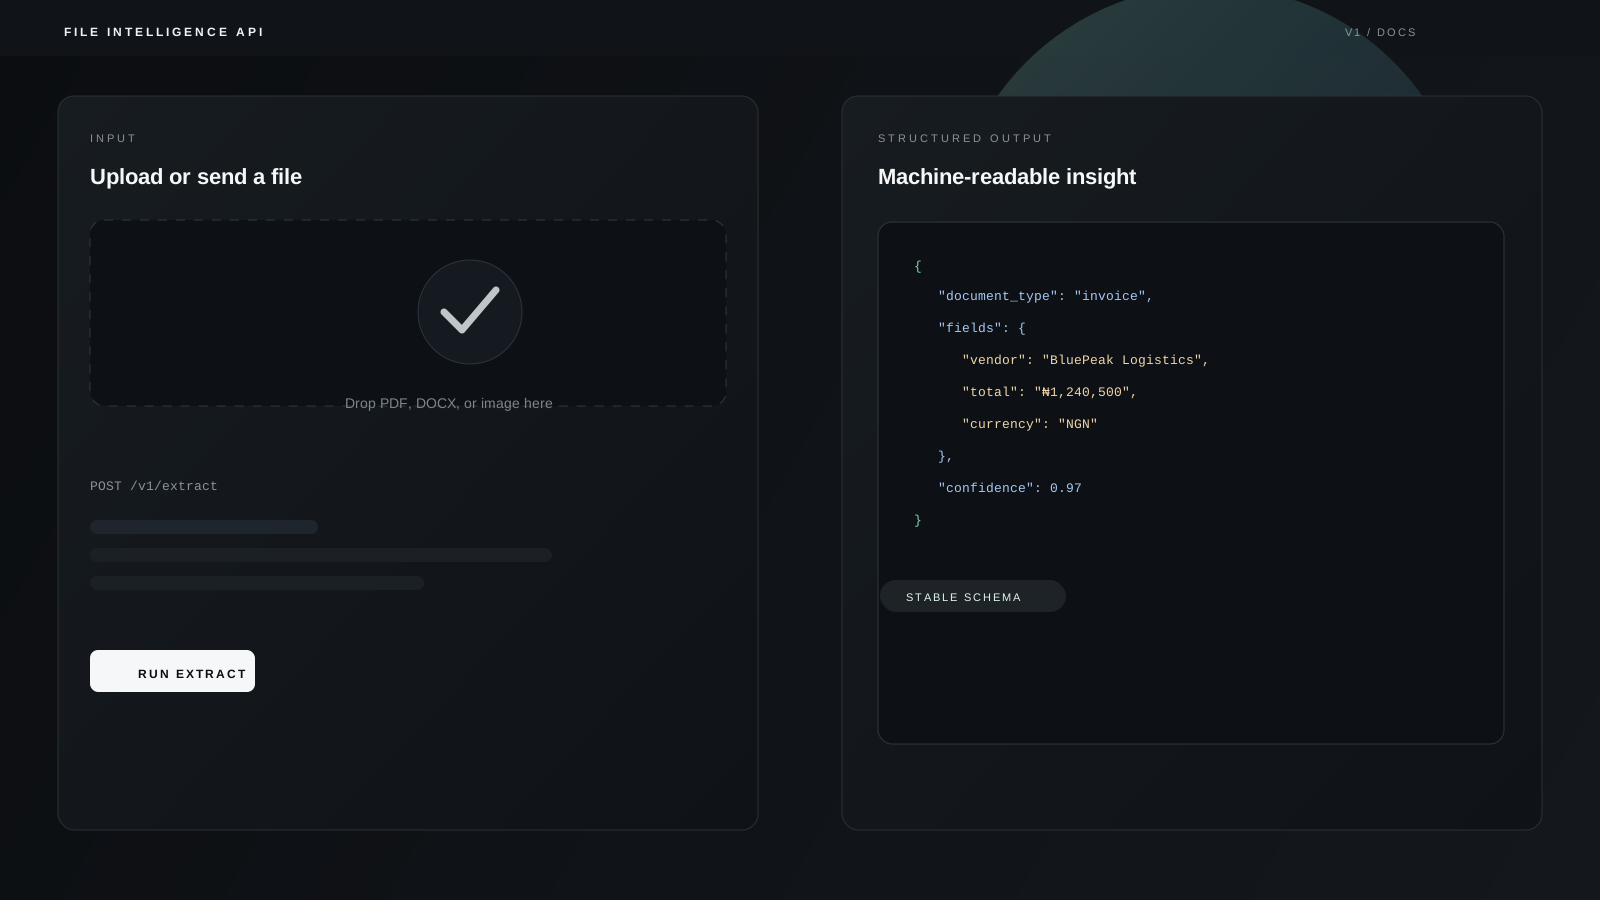
An API-first document intelligence project that turns uploaded files into structured, machine-readable output for downstream systems and workflows.
- Category
- AI · API · Document Intelligence
- Year
- 2025
- Role
- Software Engineer
- Status
- LIVE
The idea
The project exists to make raw documents usable as data. Files are treated as inputs to a predictable pipeline that extracts relevant structure instead of leaving builders to parse everything manually.
The problem
Most systems still treat documents as blobs. That creates friction for any workflow that needs reliable extraction, classification, or downstream processing without custom one-off parsing logic.
The approach
The design is intentionally API-first. The system is structured to receive files, process them, and return structured output with a stable contract that product teams can depend on.
My role
Michael designed and built the API and processing pipeline around reliable extraction, structured responses, and a backend contract that other product surfaces can integrate with.
The build
The work centers on a FastAPI backend and a structured extraction flow designed to be called by other systems. The project is not framed around vague AI promises; it is built as a real operational pipeline with a focused contract.
- Python
- FastAPI
- TypeScript
- React
- AI
- APIs
Engineering
The implementation emphasizes predictable data flow, typed responses, and a clear separation between ingestion, processing, and output. This keeps the system easier to integrate and more resilient to iteration.
Product
The product value is in operational utility: less manual processing, a clearer contract for downstream systems, and data that is easier to work with in other applications.
Details
The project is live at the API endpoint and is designed to be called by other services. The public repository provides the code surface for the work while the deployed API remains the operational product layer.
Status
LIVE.